Real-world applications of artificial intelligence (AI) are specialized machine learning models and automated decision pipelines deployed within production software to solve defined operational problems. Rather than functioning as autonomous general intelligences, these systems analyze high-dimensional data, predict equipment failures, flag payment anomalies, and assist human professionals across industries including healthcare, manufacturing, finance, and environmental monitoring.
Moving machine learning from experimental notebooks to live business operations requires rigorous infrastructure, continuous monitoring, and clear risk boundaries. Understanding where practical AI delivers measurable returns—and where operational constraints restrict its utility—is essential for technical leaders evaluating deployment options.
Quick Take: Practical AI in Enterprise Environments
Production artificial intelligence centers on narrow, task-specific systems trained on structured tables, unstructured text, or high-velocity sensor telemetry. The most effective deployments share three foundational traits:
Targeted Problem Scopes: High-performing implementations automate discrete, repetitive decisions—such as classifying radiographic scans or scoring transaction risks—rather than attempting generalized reasoning.
Engineered Data Foundations: Real-world models depend on reliable ingestion pipelines, low-latency feature stores, and vector indexing systems rather than raw algorithm complexity alone.
Human-in-the-Loop Safeguards: High-stakes workflows in clinical medicine, credit adjudication, and industrial automation enforce deterministic fallback rules and mandatory specialist sign-off.
Core Architecture: How Machine Learning Operates in Production
Deploying AI outside academic test environments requires an integrated software stack that bridges raw data sources with live application programming interfaces (APIs). Machine learning models do not operate in isolation; they exist as nodes inside broader software pipelines that collect telemetry, normalize data structures, compute inferences, and log model behavior for auditability.
A standard enterprise deployment pipeline consists of four sequential stages:
- Telemetry Ingestion and Feature Extraction: Raw data from web traffic, internet-of-things (IoT) plant sensors, or transactional ledgers is cleaned, timestamped, and transformed into numeric feature vectors stored inside an enterprise data platform.
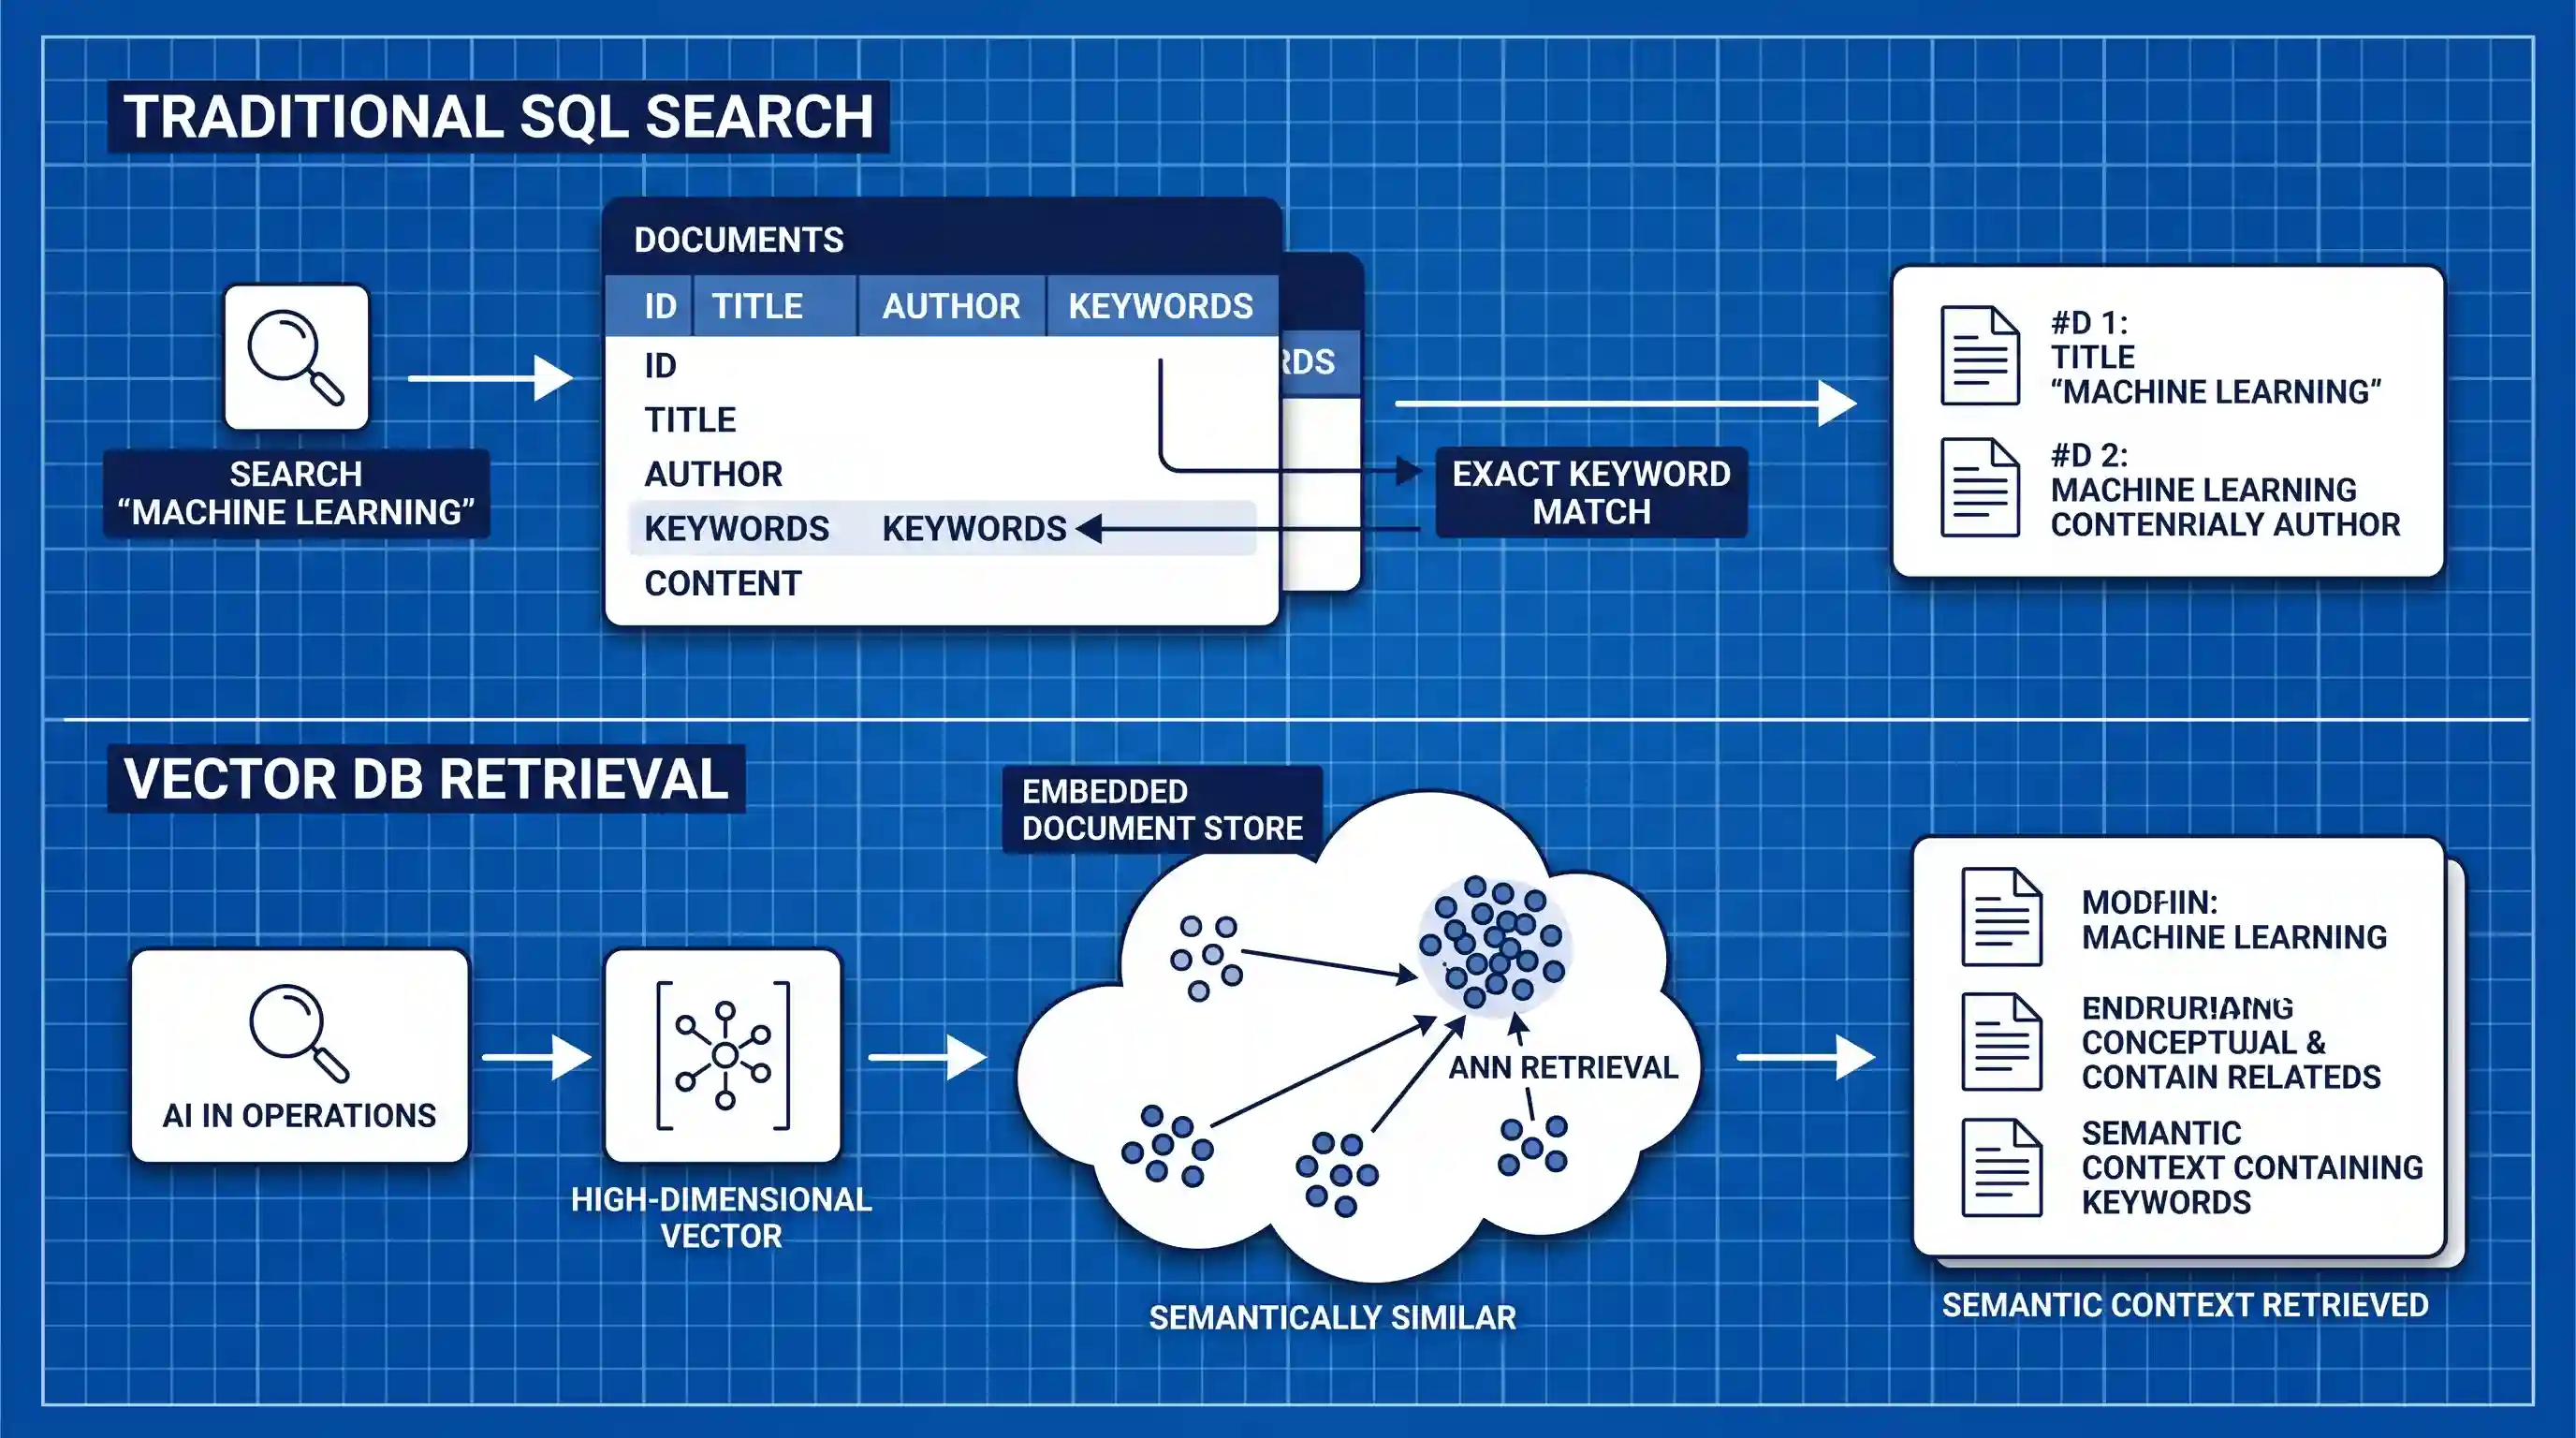
- Vector Storage and Indexing: For unstructured text, image, and audio data, specialized databases store mathematical embeddings. The Milvus vector database documentation outlines how high-dimensional vectors are organized into indexed collections to enable sub-second approximate nearest-neighbor search for semantic retrieval.
- Inference Execution: The trained model scores new observations. Depending on operational latency budgets, inference runs locally on edge processors, in microservice containers hosted on cloud infrastructure, or through asynchronous batch clusters.
- Drift Monitoring and Telemetry Auditing: Production tools continuously evaluate input distributions and prediction confidence scores to identify data drift, concept drift, or sudden degradation caused by changing real-world conditions.
Designing these systems requires integrating with reliable enterprise data pipeline architecture to prevent training-serving skew, where production data inputs subtly deviate from the datasets used during offline development.
High-Impact Industrial Applications in Production
While experimental research explores theoretical capabilities, practical enterprise investment focuses on domains where machine learning delivers measurable cost reductions, throughput increases, or error-rate improvements.
Healthcare: Clinical Imaging, Diagnostic Triaging, and Oncology
In clinical medicine, artificial intelligence serves primarily as an assistive diagnostic second-reader. Convolutional neural networks (CNNs) and vision transformers analyze digital imaging files, including computerized tomography (CT) scans, magnetic resonance imaging (MRI), and digital mammography. Rather than replacing radiologists, these tools highlight subtle microcalcifications, pulmonary nodules, or ischemic strokes, sorting urgent cases to the top of physician review queues.
Regulatory oversight enforces rigorous efficacy standards before clinical deployment. The official FDA clearinghouse of authorized medical devices catalogs hundreds of software systems cleared across radiology, cardiology, and hematology. These cleared systems operate under strict clinical protocols, providing bounded diagnostic scores that support, but never supersede, licensed medical practitioner judgment.
Beyond hospital triage, pharmaceutical research organizations deploy deep generative models to evaluate protein folding structures and simulate chemical binding affinities. Machine learning algorithms screen millions of molecular candidates computationally, shortening the exploratory phase of novel therapeutics prior to laboratory synthesis.
Industrial Manufacturing and Supply Chain Predictive Maintenance
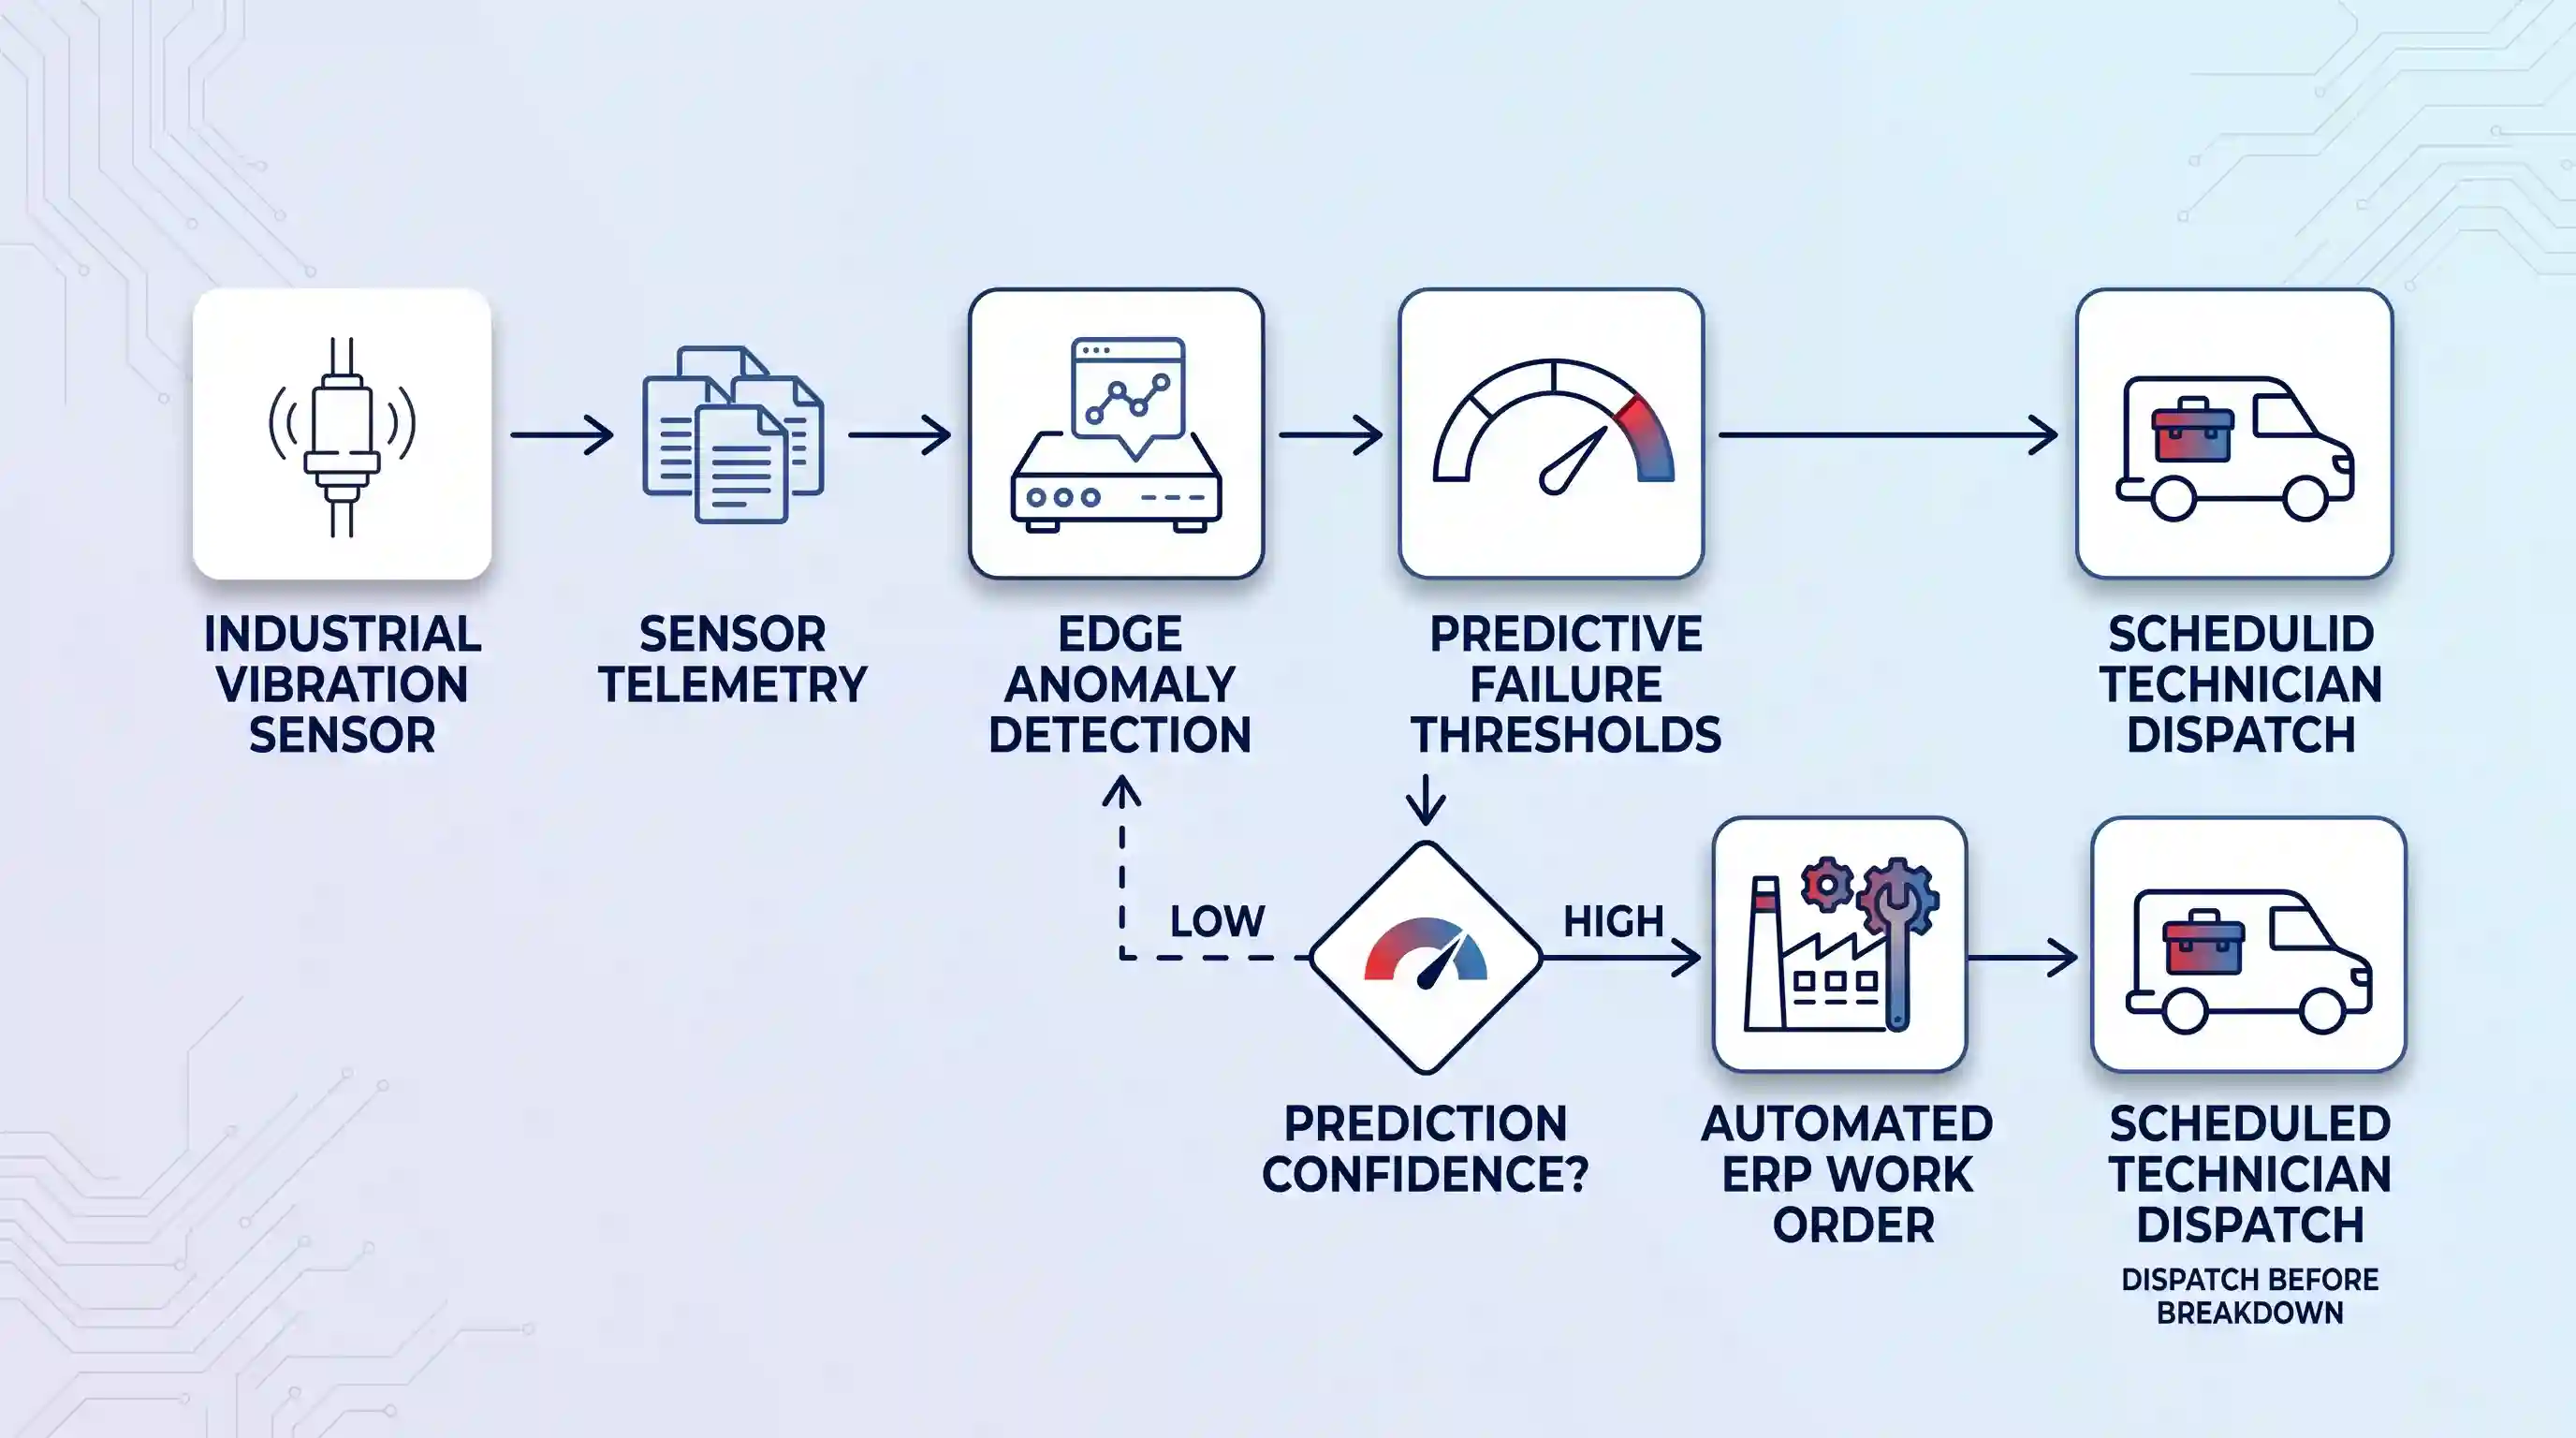
Industrial plants deploy supervised learning algorithms to monitor the operational health of critical equipment, including computer numerical control (CNC) mills, rotary compressors, and high-pressure hydraulic pumps. By processing high-frequency vibrational telemetry, thermal fluctuations, and lubrication pressure readings, models detect anomalies that precede mechanical seizure.
According to McKinsey industrial analytics research, predictive maintenance programs can reduce industrial equipment downtime by 30 to 50 percent while extending functional asset life by 20 to 40 percent. This proactive intervention shifts plant operations away from static calendar maintenance schedules toward condition-based servicing.
Furthermore, deploying modern AI in manufacturing allows fabrication facilities to automate optical quality inspection on fast-moving assembly lines and balance material inventory against forecasted supplier delays. When anomaly detection flags mechanical wear, automated connectors can dispatch work tickets directly into the facility’s existing enterprise resource planning software, reducing manual intervention across the shop floor.
Financial Services: Real-Time Fraud Interception and Algorithmic Risk
Retail banking networks and payment processors manage massive transaction volumes requiring sub-100-millisecond risk determinations. Rule-based static filters fail to counter distributed card fraud and credential stuffing attacks because bad actors quickly decipher hardcoded parameter boundaries. Machine learning classifiers analyze hundreds of contextual attributes simultaneously, evaluating cardholder geolocation, velocity of spend, merchant categories, and behavioral typing cadences.
Production systems like the Mastercard Decision Intelligence architecture use neural decision engines to compute predictive risk scores during the authorization step. This real-time scoring prevents fraudulent transfers while minimizing false declines that frustrate legitimate cardholders.
In wholesale credit underwriting, gradient-boosted decision trees analyze borrower cash-flow trends, repayment histories, and commercial counterparty relationships. However, financial regulations mandate model explainability; algorithms that determine lending eligibility must generate concrete adverse action notices detailing which specific financial metrics produced an unfavorable decision.
Autonomous Mobility: Sensor Fusion and Fleet Telemetry
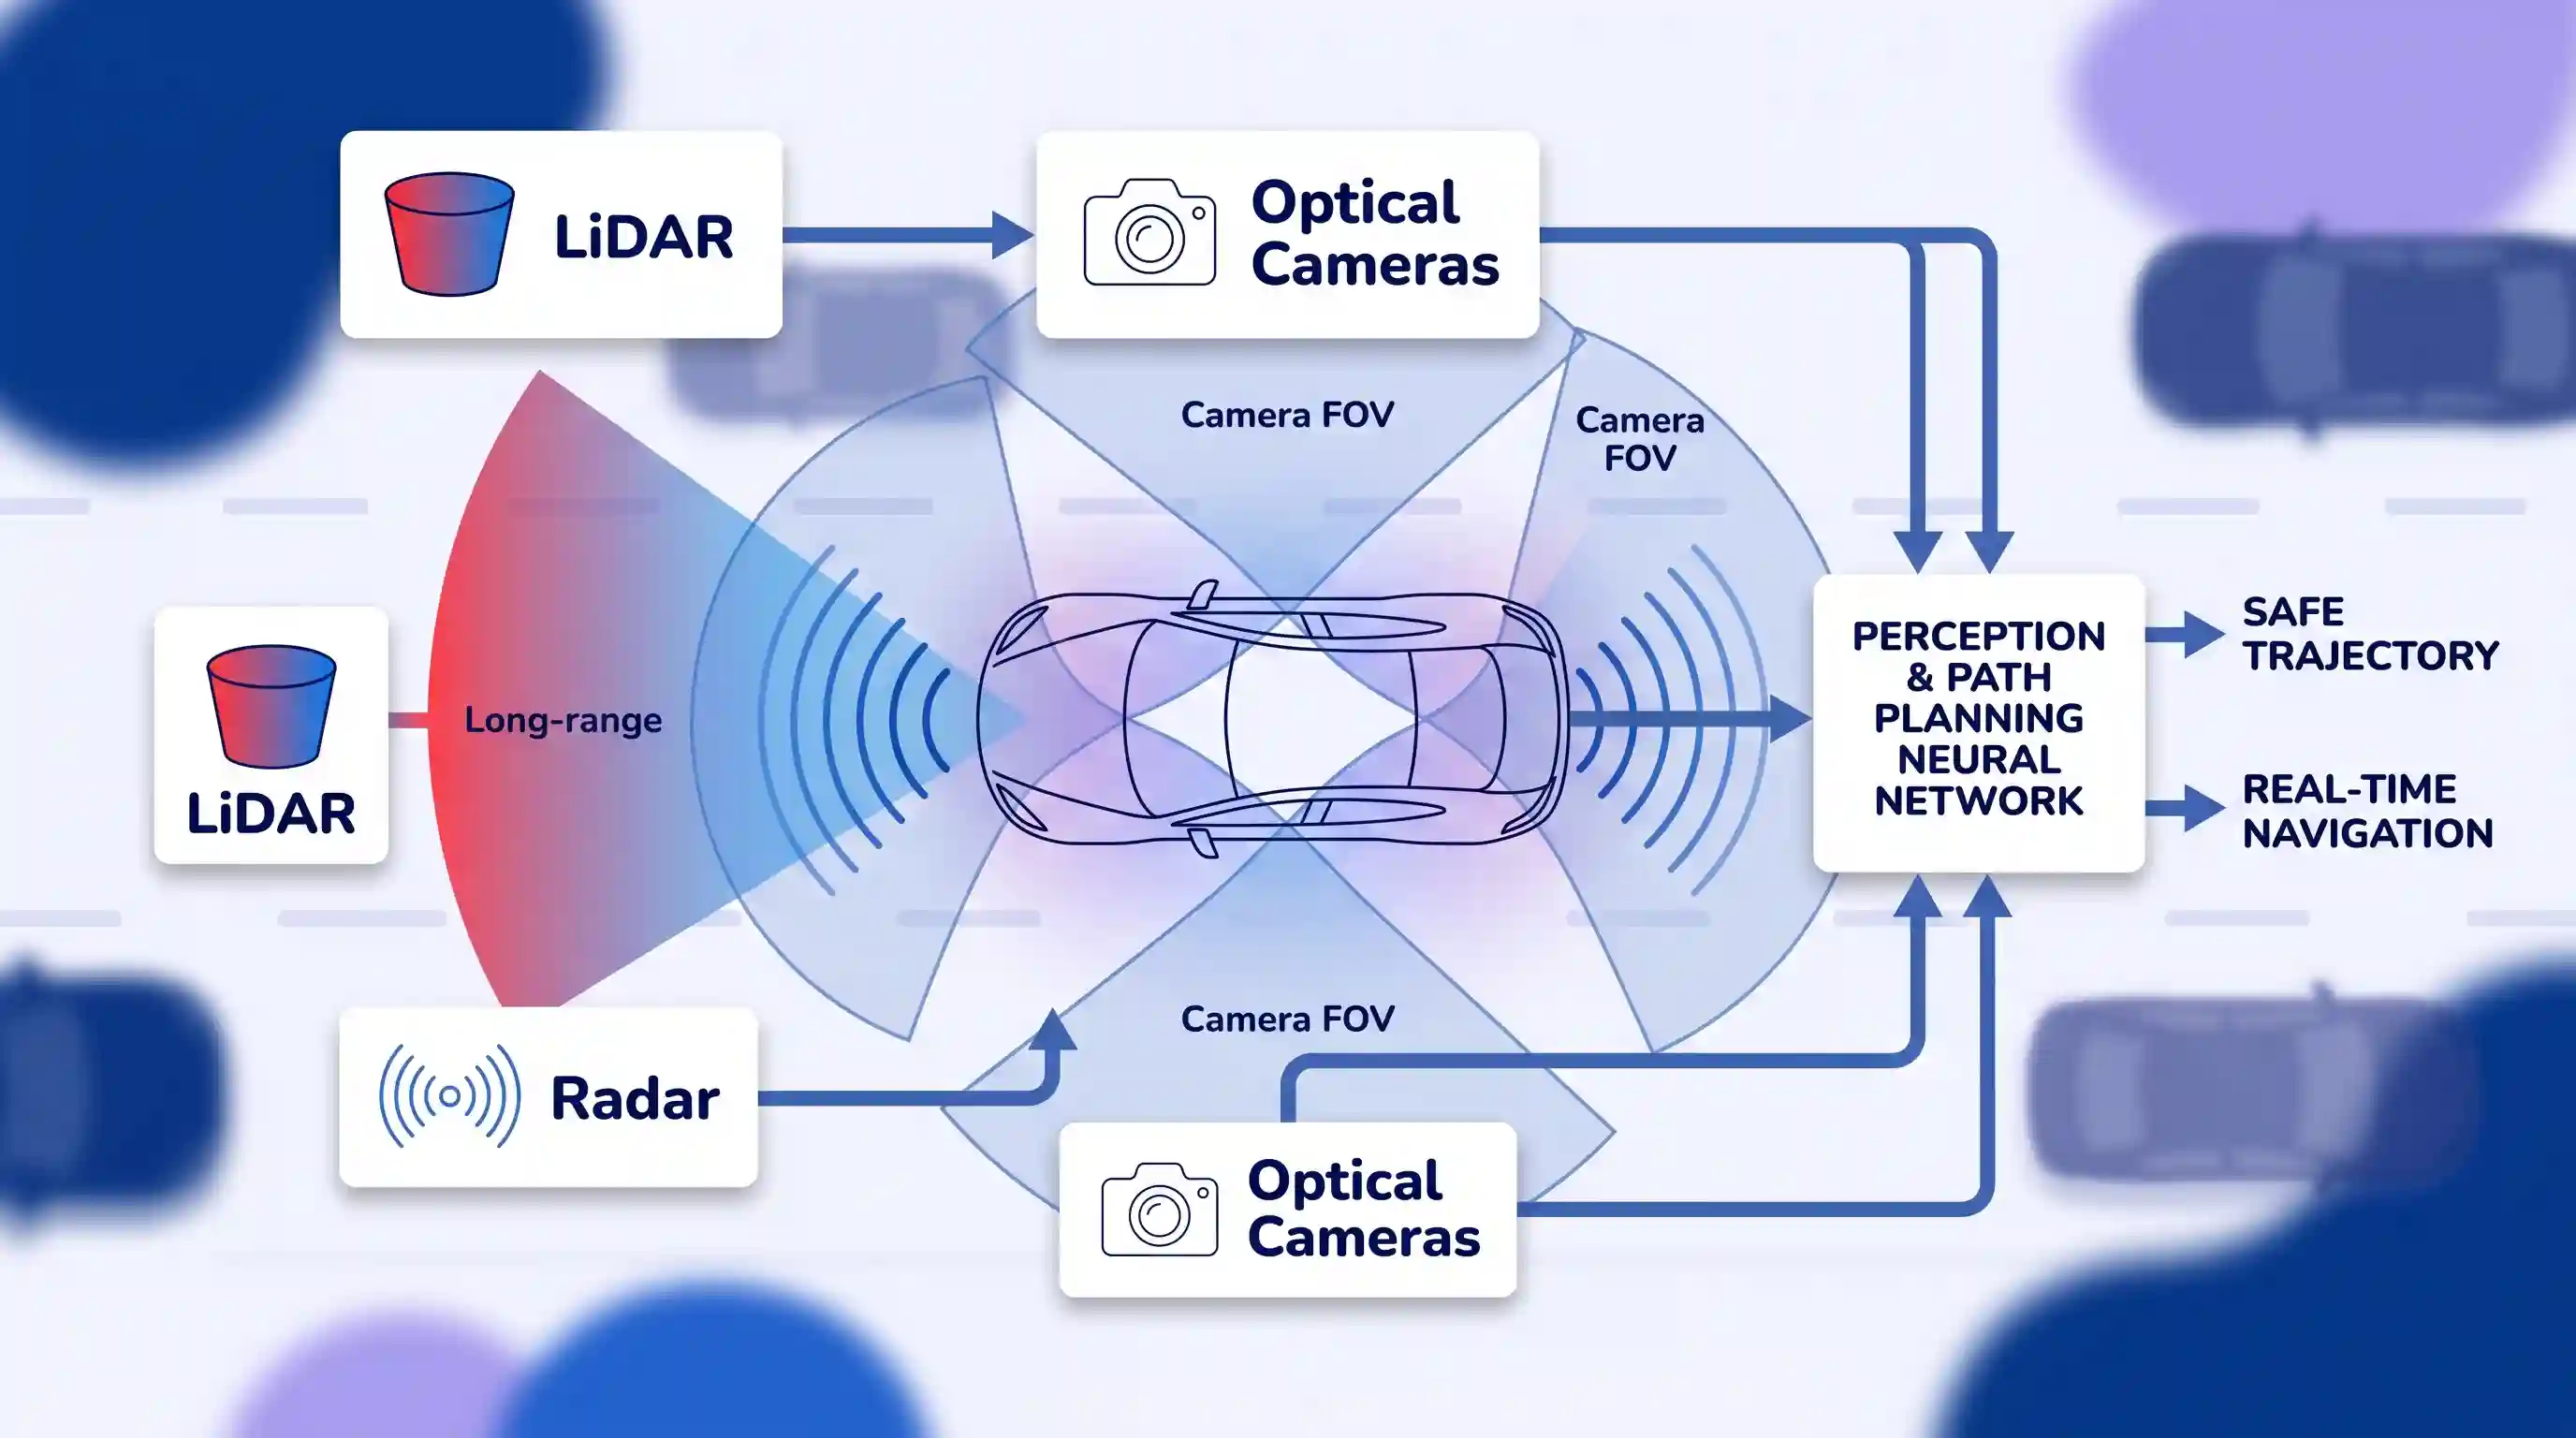
The autonomous transportation sector has advanced from controlled test tracks to commercial robotaxi deployments in major urban markets. True self-driving relies on sensor fusion pipelines that merge data streams from LiDAR, millimeter-wave radar, and high-resolution optical cameras into a unified spatial representation of the surrounding environment.
According to Waymo commercial safety benchmark data, operating commercial autonomous fleets have accumulated over 220 million fully autonomous rider-only miles, showing an 82% to 94% reduction in injury-causing crashes compared to human drivers in the same operating areas. Deep neural networks handle perception, predicting the trajectory of pedestrians, cyclists, and oncoming vehicles, while deterministic path-planning algorithms compute steering geometry and braking curves within safety boundaries.
Climate Intelligence and Deforestation Tracking
Environmental data analysis benefits significantly from computer vision applied to Earth observation satellites. Conventional forestry surveys historically required manual ground inspection or delayed annual reports, allowing unlawful logging operations to clear hundreds of hectares before forestry authorities could intervene.
Modern conservation initiatives deploy convolutional networks to process multi-spectral imagery. The Global Forest Watch satellite monitoring program uses cloud computing and machine learning to analyze near-real-time satellite feeds from Landsat and Sentinel constellations, issuing automated alerts when tree canopy loss is detected.
Similarly, non-profit institutions and enterprise initiatives focused on monitoring deforestation combine satellite radar with airborne LiDAR data to verify biomass volume. This precise measurement helps carbon credit registries confirm that protected forest tracts remain intact over multi-year verification periods.
Enterprise Data Retrieval and Operational Customer Support
Customer service and internal enterprise search have transitioned away from brittle decision trees toward retrieval-augmented generation (RAG) architectures. Early customer service bots depended on strict keyword triggers, causing conversational breakdowns when users phrased inquiries colloquially.
Production conversational agents pair natural language processing with vector similarity retrieval. When an employee or customer submits a query, the system extracts the semantic intent, queries an internal document knowledge base for authoritative source paragraphs, and instructs a large language model to synthesize an answer derived solely from those verified excerpts. Implementing practical natural language processing chatbots reduces tier-one ticket backlogs while mitigating the hallucination risks common to ungrounded generative models.
Real-World Implementation Trade-Offs
Selecting an AI architecture involves direct technical trade-offs among latency, operational hosting costs, data privacy, and infrastructural maintenance. No single deployment topology fits every operational scenario.
| Deployment Paradigm | Inference Latency | Hosting and Compute Cost Profile | Network and Privacy Profile | Primary Enterprise Use Cases |
|---|---|---|---|---|
| Embedded Edge AI | Low (sub-10ms) | High upfront device cost; zero per-query cloud compute fees | Full on-device privacy; operates completely offline | Autonomous vehicle collision avoidance, shop-floor machine vision, wearable health monitors |
| Cloud Microservice APIs | Moderate (100ms – 500ms) | Variable operational expense; scales linearly with request volume | Requires encrypted transit; subject to regional compliance rules | Real-time credit card fraud scoring, dynamic pricing engines, automated document OCR |
| Asynchronous Batch Pipelines | High (Minutes to Hours) | Optimized cost via spot instances and scheduled compute windows | Data consolidated in internal data lakes before execution | Nightly churn modeling, predictive inventory replenishment, satellite canopy analysis |
| Retrieval-Augmented Generation (RAG) | Moderate to High (500ms – 2000ms) | Compound costs: vector indexing plus generative token usage | Hybrid: private vector store paired with guarded LLM endpoints | Enterprise knowledge retrieval, contract compliance auditing, automated customer support |
Balancing these operational approaches requires diligent cloud infrastructure cost optimization to prevent runaway token billing and unconstrained cloud GPU cluster consumption.
Common Misconceptions About Practical AI Deployment
Commercial marketing often obscures the operational realities of machine learning engineering. Teams evaluating real-world deployments frequently encounter three persistent myths:
Production machine learning models are static artifacts once exported. They do not continuously modify their weights while serving live API requests. Self-updating models in live environments risk catastrophic forgetting and unconstrained behavioral drift; retraining occurs in isolated, validated staging environments prior to canary rollouts.Myth 2: Foundation models eliminate the need for domain-specific tabular data.
While generative models handle unstructured language effectively, enterprise operations rely heavily on tabular data: transaction histories, sensor time-series, and ERP records. Classical gradient-boosted algorithms (such as XGBoost and LightGBM) regularly outperform deep neural networks on structured tabular datasets in training speed, compute efficiency, and inference latency.Myth 3: High validation accuracy guarantees business value.
An anomaly detection model with 99% accuracy can be operationally useless if it triggers 200 false alarms daily on an assembly line. When line operators face persistent false positives, they inevitably ignore system alerts entirely, rendering the technical deployment ineffective.
Technical Limitations and Operational Edge Cases
Every practical AI system has hard operational boundaries. Failing to plan for these constraints results in brittle production software and unexpected system outages.
The primary technical bottlenecks include:
- Data Drift and Distribution Shifts: A fraud detection model trained on pre-holiday spending patterns degrades when seasonal purchasing shifts consumer behaviors. Continuous drift detection pipelines must track input distributions and trigger automated alerts when confidence scores drop below acceptable thresholds.
- High-Dimensional Query Latency: As vector collections expand into millions of high-dimensional embeddings, retrieval latencies increase. Engineering teams must implement quantization techniques and Hierarchical Navigable Small World (HNSW) indexing to keep semantic search response times within practical boundaries.
- Training-Serving Skew: Discrepancies between feature calculation in offline batch pipelines and online real-time APIs introduce subtle inference errors that escape standard software unit tests.
- Algorithmic Bias and Regulatory Compliance: Models trained on historical enterprise records reproduce historical human biases. Organizations must implement formal model governance frameworks to systematically audit training datasets for demographic disparities and ensure compliance with emerging international data protection standards.
Key Takeaways
- Real-world artificial intelligence focuses on narrow, task-specific models integrated into broader data pipelines, not autonomous general intelligence.
- High-impact enterprise applications center on domains with clear economic metrics: predictive equipment maintenance, clinical diagnostic triaging, real-time fraud scoring, and satellite environmental monitoring.
- Hardware topology must match operational latency budgets, balancing sub-10ms edge inference against higher-latency cloud batch and RAG architectures.
- Data infrastructure, feature engineering, and continuous drift monitoring determine operational success far more than choosing novel algorithmic architectures.
- Production deployments require explicit human-in-the-loop escalation paths and model governance to catch false positives and manage regulatory compliance.
Frequently Asked Questions
How does real-world AI differ from generative consumer tools like ChatGPT?
Generative consumer tools provide broad, open-ended natural language interaction hosted on generalized public servers. In contrast, real-world enterprise AI systems consist of purpose-built, narrow models—such as computer vision classifiers, time-series anomaly detectors, or retrieval-augmented pipelines—deployed inside secured enterprise architectures to solve specific operational tasks under strict latency, privacy, and accuracy parameters.
What is the biggest technical obstacle when moving AI models to production?
The most persistent technical hurdle is maintaining data pipeline consistency and managing data drift. Models trained on historical, curated datasets often fail when encountering unexpected real-time input formats, corrupted sensor readings, or changing user behaviors in live production environments, necessitating continuous telemetry monitoring and robust data validation gates.
Why do companies prefer vector databases over relational databases for AI retrieval?
Relational databases index data based on exact keyword matches, numerical values, or categorical tags. Vector databases index high-dimensional numeric embeddings generated by machine learning models, allowing systems to perform mathematical similarity searches based on conceptual meaning rather than exact keyword overlap, which is essential for semantic search and retrieval-augmented generation.
When should an organization choose edge AI instead of cloud-hosted models?
Edge AI is necessary when applications require sub-10-millisecond response times, operate in environments with intermittent or non-existent internet connectivity, or process sensitive biometric and visual telemetry that cannot leave local hardware due to strict regulatory privacy requirements. Examples include industrial robotic safety cutoffs, automotive sensor perception, and local medical imaging hardware.
