Data backup and recovery help a business limit the damage caused by deletion, corruption, system failure, cyberattacks, and other disruptions. Their real value, however, depends on whether the organization can restore the right data and systems to a trustworthy state within an acceptable amount of time.
That distinction matters because successfully creating backup copies does not automatically mean a business can recover from an incident. A useful recovery capability connects backup copies with recovery priorities, tested restoration procedures, protected credentials and configuration, and clear objectives for how much data loss and downtime the organization can tolerate.
Backup and Recovery Are Related, but They Are Not the Same
Backup and recovery are often discussed together, but they perform different jobs. A backup is an additional copy of data that can be used when the original becomes unavailable, damaged, deleted, or corrupted. Recovery is the broader process of returning data, applications, and supporting systems to a usable state after a disruption.
What backup does
Backup creates recoverable copies of information. Depending on the environment, those copies may include databases, documents, application data, system images, configuration files, or other information that the business needs to operate.
The copies may be stored on local infrastructure, removable media, another site, or cloud infrastructure. Choosing between cloud backup and local backup is therefore an architectural decision rather than part of the definition of backup itself. The important requirement is that the chosen copies remain available and usable when the production data is not.
What recovery does
Recovery begins when the organization needs to use those copies. It can involve restoring individual files, databases, application servers, virtual machines, configuration, authentication systems, and other dependencies needed to return a service to operation.
The difference is easy to see in practice. A company may have a current database backup, but that copy alone will not restore an application if its configuration, encryption keys, identity service, or supporting infrastructure are unavailable. The backup provides source data for recovery; it is not the entire recovery process.
Where disaster recovery and business continuity fit
Disaster recovery is broader than restoring a file. It coordinates the restoration of technology and services after a serious disruption. Business continuity is broader still because it considers how critical business functions will continue while normal systems, facilities, staff, or suppliers are disrupted.
NIST’s contingency-planning guidance describes a process for identifying contingency requirements and priorities, selecting recovery strategies, testing plans, and maintaining them. That makes backup an important resilience control, but not a substitute for disaster recovery, incident response, or business continuity planning.
Why Backup and Recovery Matter to a Business
They limit the impact of accidental deletion, corruption, and system failure
Business data can become unavailable for ordinary reasons as well as dramatic ones. A user may delete a folder, an update may damage an application, a database may become corrupted, storage hardware may fail, or a configuration change may break a service.
A recoverable copy gives the organization a known point from which it can restore affected information instead of attempting to reconstruct everything manually. That can be especially important when data changes frequently or when the affected system supports transactions, customer records, finance, operations, or other time-sensitive work.
They reduce the operational effect of downtime
Data loss is rarely only a storage problem. When the affected information supports an application or workflow, employees may lose access to the tools they need to work, customers may be unable to use a service, orders may stop moving, or other systems may lose an important dependency.
Recovery planning therefore focuses on more than whether a copy exists. It asks which services should return first and how quickly they need to be restored. NIST contingency guidance emphasizes evaluating information systems and operations to determine recovery requirements and priorities rather than treating every system identically.
They preserve a recovery path after ransomware
Ransomware can encrypt production data and may also target backup repositories that remain reachable from compromised systems. The U.S. Cybersecurity and Infrastructure Security Agency recommends maintaining offline, encrypted backups of critical data and regularly testing their availability and integrity. CISA also warns that ransomware actors may delete or encrypt accessible backups.
Protected backups can therefore provide a restoration path, but they do not prevent ransomware and they do not eliminate every consequence of an attack. An organization may still need to contain the incident, remove malicious access, rebuild systems, rotate credentials, investigate possible data exposure, verify restored assets, and meet any applicable notification or response obligations.
They support recovery after physical and infrastructure disruption
Recovery may also be required after storage failure, equipment damage, a facility problem, a cloud or network disruption, or another event that makes the original environment unavailable. The appropriate design depends on which failures the business needs to survive. Keeping every copy in the same failure domain, for example, can leave the organization without a usable recovery source when that environment is lost.
The Most Important Question Is Not “Do We Have a Backup?”
A more useful question is: Can the business restore what it needs, to a trustworthy state, quickly enough?
Two planning concepts help turn that question into measurable requirements: Recovery Point Objective and Recovery Time Objective.
Recovery Point Objective: how much recent data can the business afford to lose?
A Recovery Point Objective, or RPO, identifies the point in time to which data must be recovered after an outage. NIST defines RPO as the point in time to which data must be recovered following an outage.
If a business can tolerate losing up to four hours of recent changes, its backup and replication design can be different from one that must preserve nearly every transaction. The right objective depends on how the data is used, how frequently it changes, and what losing recent changes would mean operationally.
Recovery Time Objective: how long can the service remain unavailable?
A Recovery Time Objective, or RTO, concerns the acceptable recovery period. NIST defines RTO as the overall length of time system components can remain in the recovery phase before the delay negatively affects the organization’s mission or business processes.
For example, a public archive that changes infrequently may tolerate a longer recovery period than an order-processing system that employees and customers depend on throughout the day. The difference should influence recovery architecture, staffing, automation, redundancy, and testing.
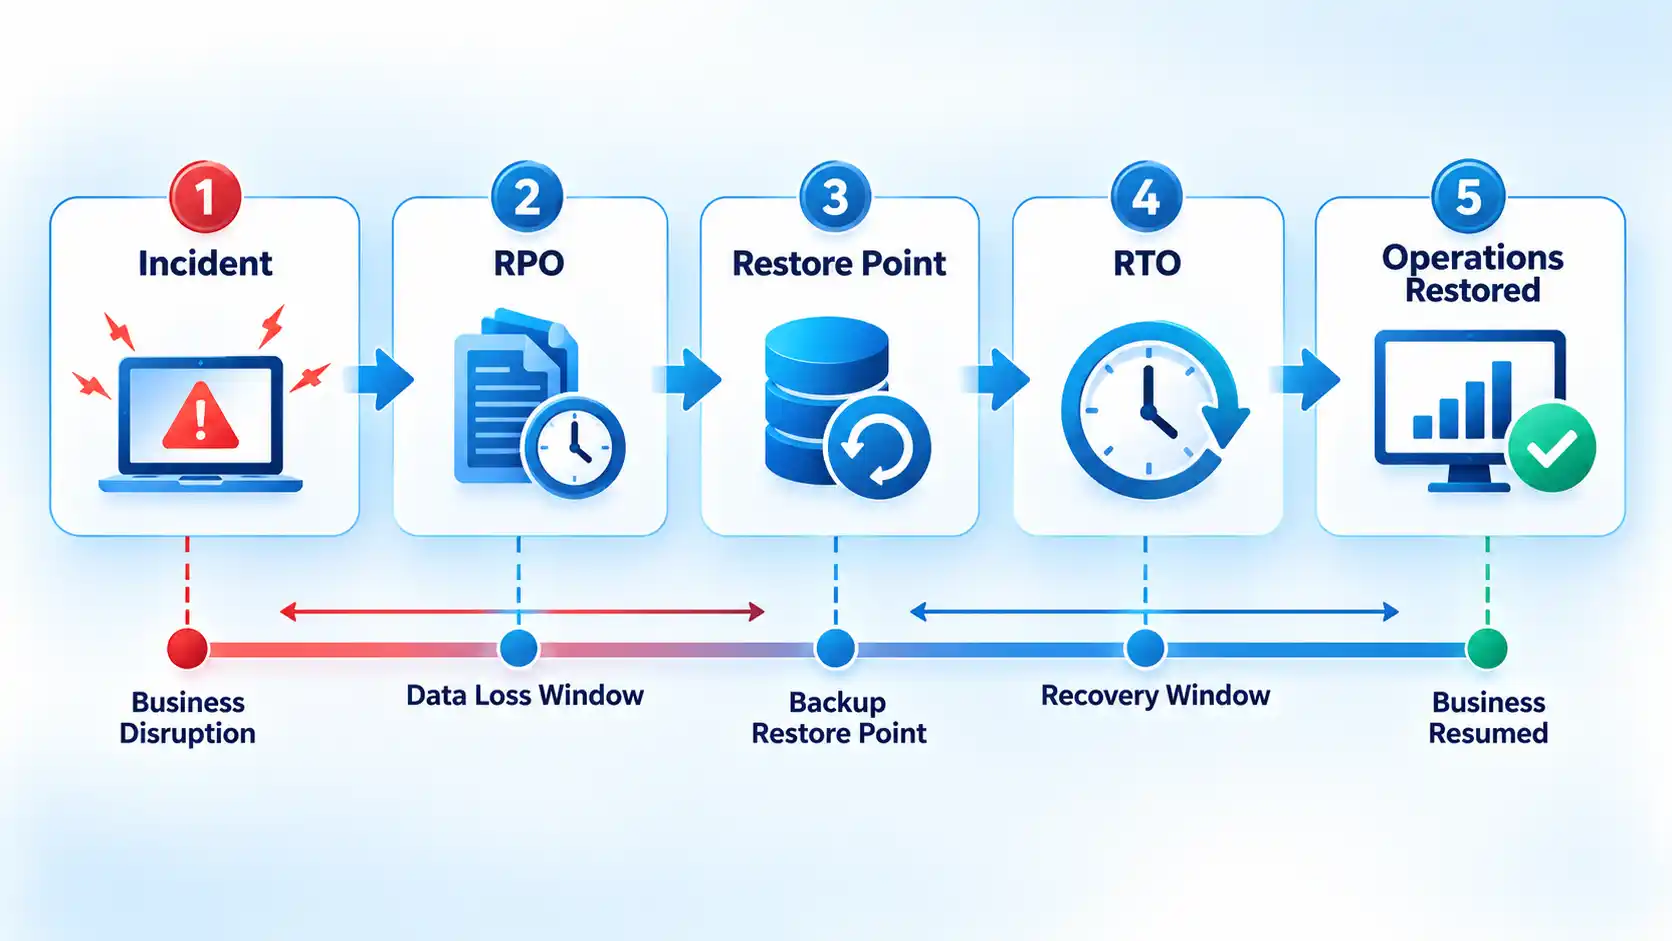
RPO and RTO also show why there is no universal backup schedule that fits every business. Backup frequency should follow the amount of recent data the organization can tolerate losing, while recovery design should reflect how quickly the affected service must return.
Why Having Backup Copies Is Not Enough
The copies must survive the same incident
A backup cannot help if the incident that damages production also destroys the recovery copy. That is why ransomware guidance emphasizes separation, access control, offline copies, encryption, and protections against deletion or overwrite.
Businesses may use on-premises systems, cloud platforms, or managed data backup and recovery services, but the important question is whether the chosen setup can protect the required data and restore it within the organization’s recovery objectives.
A deeper business backup strategy should therefore account for failure domains, access separation, retention, recovery objectives, and testing rather than choosing storage based only on convenience.
The copies must be trustworthy
A backup may exist but still be unsuitable for recovery if it is incomplete, corrupted, inaccessible, encrypted with a lost key, too old for the required RPO, or compromised by the same incident that damaged production.
Integrity testing matters for the same reason. CISA recommends regularly testing both the availability and integrity of critical backups so that a recovery plan does not depend on copies that cannot actually be used when an incident occurs.
The restore process must be tested
A successful backup job usually proves that the backup system completed a copy operation. It does not prove that the business can restore the data, reconstruct dependencies, authenticate to the restored service, meet its recovery objectives, or return the system safely to production.
Restore testing can expose missing data, incomplete procedures, unusable media, forgotten credentials, unavailable encryption keys, incorrect permissions, dependency problems, or recovery times that are much longer than expected. Repeated backup restore failures can therefore indicate a recovery-design problem even when scheduled backup jobs appear healthy.
Recovery must include dependencies
Business services rarely consist of one data file. A useful recovery plan may need application software, database engines, system configuration, certificates, identity and access services, network settings, infrastructure definitions, license information, and third-party dependencies in addition to the business data itself.
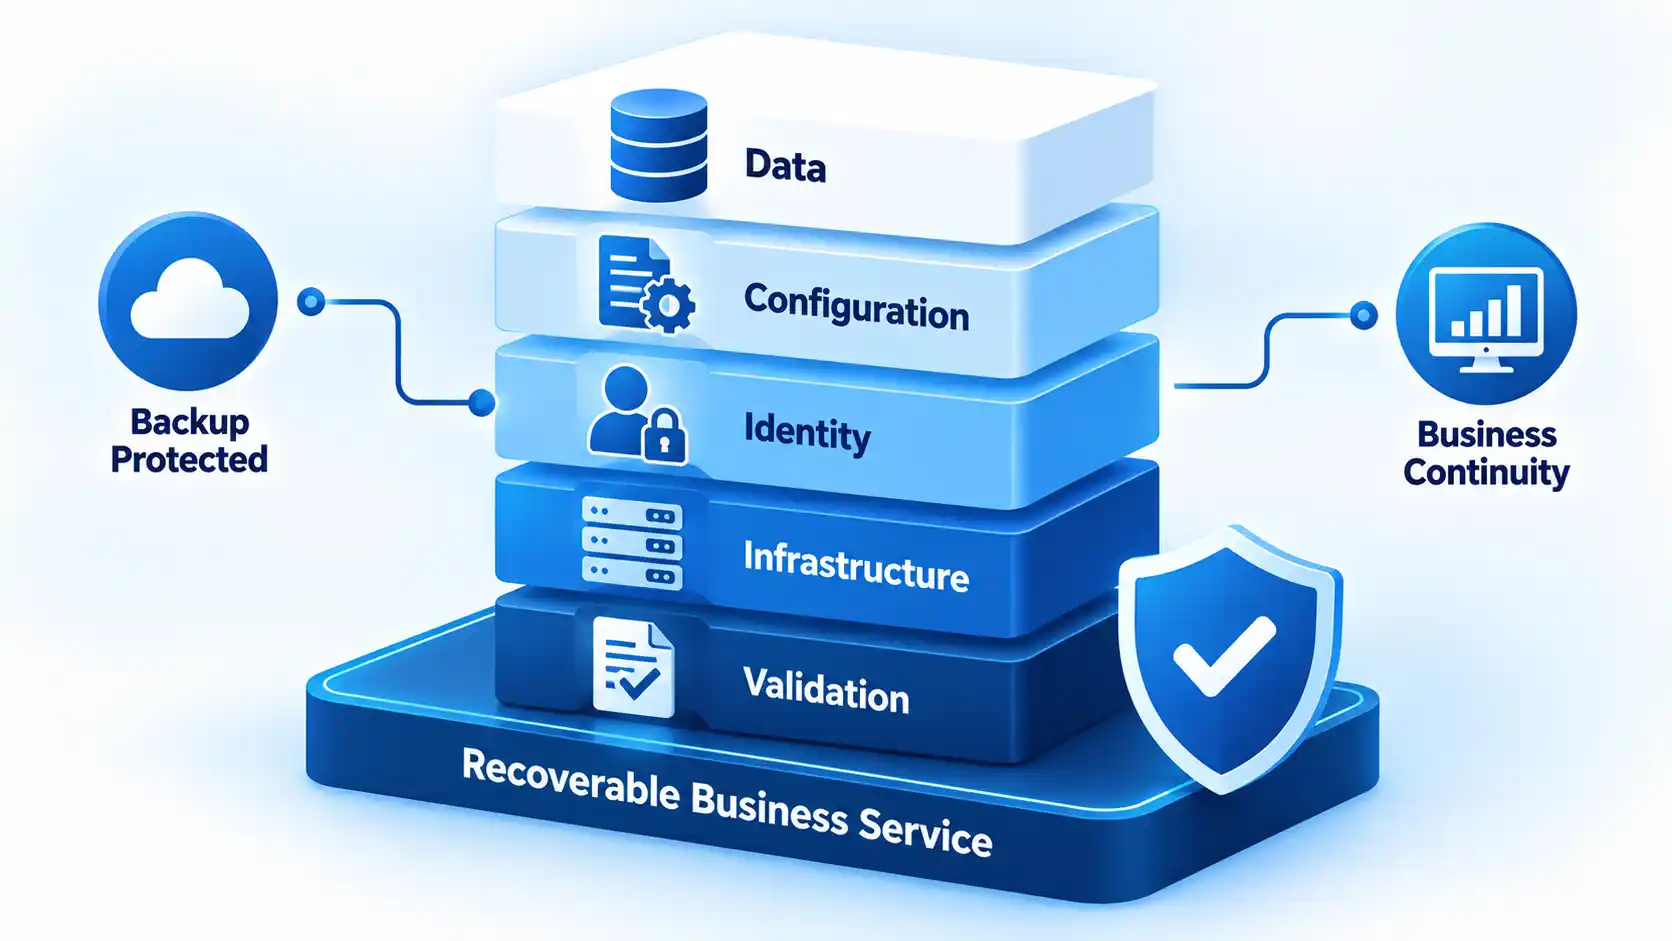
This is another reason restoration should be evaluated at the service level. Recovering the database is not the same as recovering a working customer portal if the application cannot authenticate users or connect to the restored database.
Backup and Recovery During a Ransomware Incident
Backups are an important ransomware recovery control, but they are not a ransomware-prevention control. They do not stop phishing, credential theft, vulnerability exploitation, malware execution, lateral movement, or data exfiltration.
CISA advises organizations to restore data from offline, encrypted backups according to the priority of critical services and to avoid reinfecting clean systems during recovery. That means restoration should normally occur alongside containment, eradication, credential and access review, and verification that recovered systems are safe to return to operation.
The distinction is especially important because ransomware incidents can combine encryption with data theft. Even if a business restores every affected system successfully, stolen information may still create privacy, contractual, regulatory, or reputational consequences.
The Federal Trade Commission similarly advises small businesses to keep backups outside the normal network and notes that having backed-up data can support restoration after ransomware. The FTC also cautions that paying a ransom does not guarantee that data will be recovered.
Where Compliance Fits, and Where It Does Not
Backup and recovery can support regulatory and contractual obligations, but backup should not be presented as a universal compliance shortcut. Requirements depend on the jurisdiction, industry, type of information, contracts, retention rules, and other circumstances that apply to the organization.
HIPAA example
For organizations regulated by the U.S. Health Insurance Portability and Accountability Act Security Rule, contingency planning includes specific requirements related to electronic protected health information. HHS explains that regulated entities must establish procedures for backing up ePHI, restoring lost data, and continuing critical business processes in emergency mode.
The HHS audit protocol also examines backup frequency, backup security, media reliability and data integrity, restore procedures, and documentation of backup and restoration testing. Under the Security Rule, the data backup plan, disaster recovery plan, and emergency-mode operation plan are required implementation specifications; testing and revision procedures and applications-and-data criticality analysis are addressable specifications that must be handled according to the rule’s requirements.
GDPR example
The European Union’s General Data Protection Regulation takes a risk-based approach. Article 32 includes, where appropriate, the ability to restore availability and access to personal data in a timely manner after a physical or technical incident, along with a process for regularly testing, assessing, and evaluating the effectiveness of security measures.
The official GDPR text on EUR-Lex ties those measures to the risks presented by processing. An organization should therefore identify the legal and contractual requirements that actually apply to its data and activities rather than assuming that one backup practice proves compliance everywhere.
What a Business-Ready Backup and Recovery Program Should Be Able to Answer
A recovery-ready program should be able to demonstrate the following conditions rather than merely report that scheduled backup jobs completed successfully.
Verify the result
- The organization has identified which data, applications, and supporting systems are critical to operations.
- Each critical workload has a defined recovery point objective that reflects how much recent data can be lost.
- Each critical service has a recovery time objective that reflects how long the business can tolerate its unavailability.
- Required backup copies remain accessible even when the production environment or its normal administrator credentials are compromised.
- Encryption keys, credentials, configuration, application dependencies, and other recovery assets are protected and available to authorized recovery personnel.
- A recent restore test has demonstrated that the required data and systems can be recovered rather than merely copied.
- Restored data and systems are checked for integrity and, after a security incident, for signs that the original compromise remains.
- The organization knows which services should be restored first and who is authorized to initiate and manage recovery.
These checks measure recovery capability rather than backup-job activity. They also help expose a common failure mode: an organization may possess usable data copies yet still lack the credentials, configuration, dependencies, documented responsibilities, or tested process needed to bring a critical service back into operation.
Conclusion
Data backup is essential because it preserves recoverable copies of information, but business resilience depends on what happens after those copies are created. A strong recovery capability connects protected backups with realistic RPO and RTO targets, service dependencies, tested restore procedures, security controls, and clear recovery priorities.
The appropriate design will vary between organizations because the consequences of data loss and downtime are not the same for every workload. The better measure is therefore not whether a dashboard says the last backup succeeded, but whether the business has demonstrated that it can restore critical information and services to a trustworthy state within the limits the organization has defined.

💬 Comments