Ask a chat assistant to turn a rambling meeting transcript into a five-line summary and you get one before your coffee cools. Ask it to explain a billing clause and it produces something that reads like an experienced colleague wrote it. That fluency is real, and it is exactly why so many people misread what is happening behind the prompt.
When the model answers, it predicts the next small piece of text, then the next, drawing on statistical patterns absorbed from an enormous body of writing. A confident answer and a correct answer arrive in the same tone of voice, and only a check tells them apart.
A large language model is a statistical language engine. Trained on vast text, it estimates which word or word fragment is likely to come next, and it does that well enough to draft, translate, summarize, and hold a conversation. Whether it helps you depends on matching that ability to work where a person can catch the errors.
Quick Take
- What it is: a machine-learning model, usually a neural network, trained on huge amounts of text for language tasks such as generating, summarizing, translating, and analyzing.
- How it learns: pre-training teaches general language patterns by predicting the next word; fine-tuning and instruction tuning shape it into a helpful assistant.
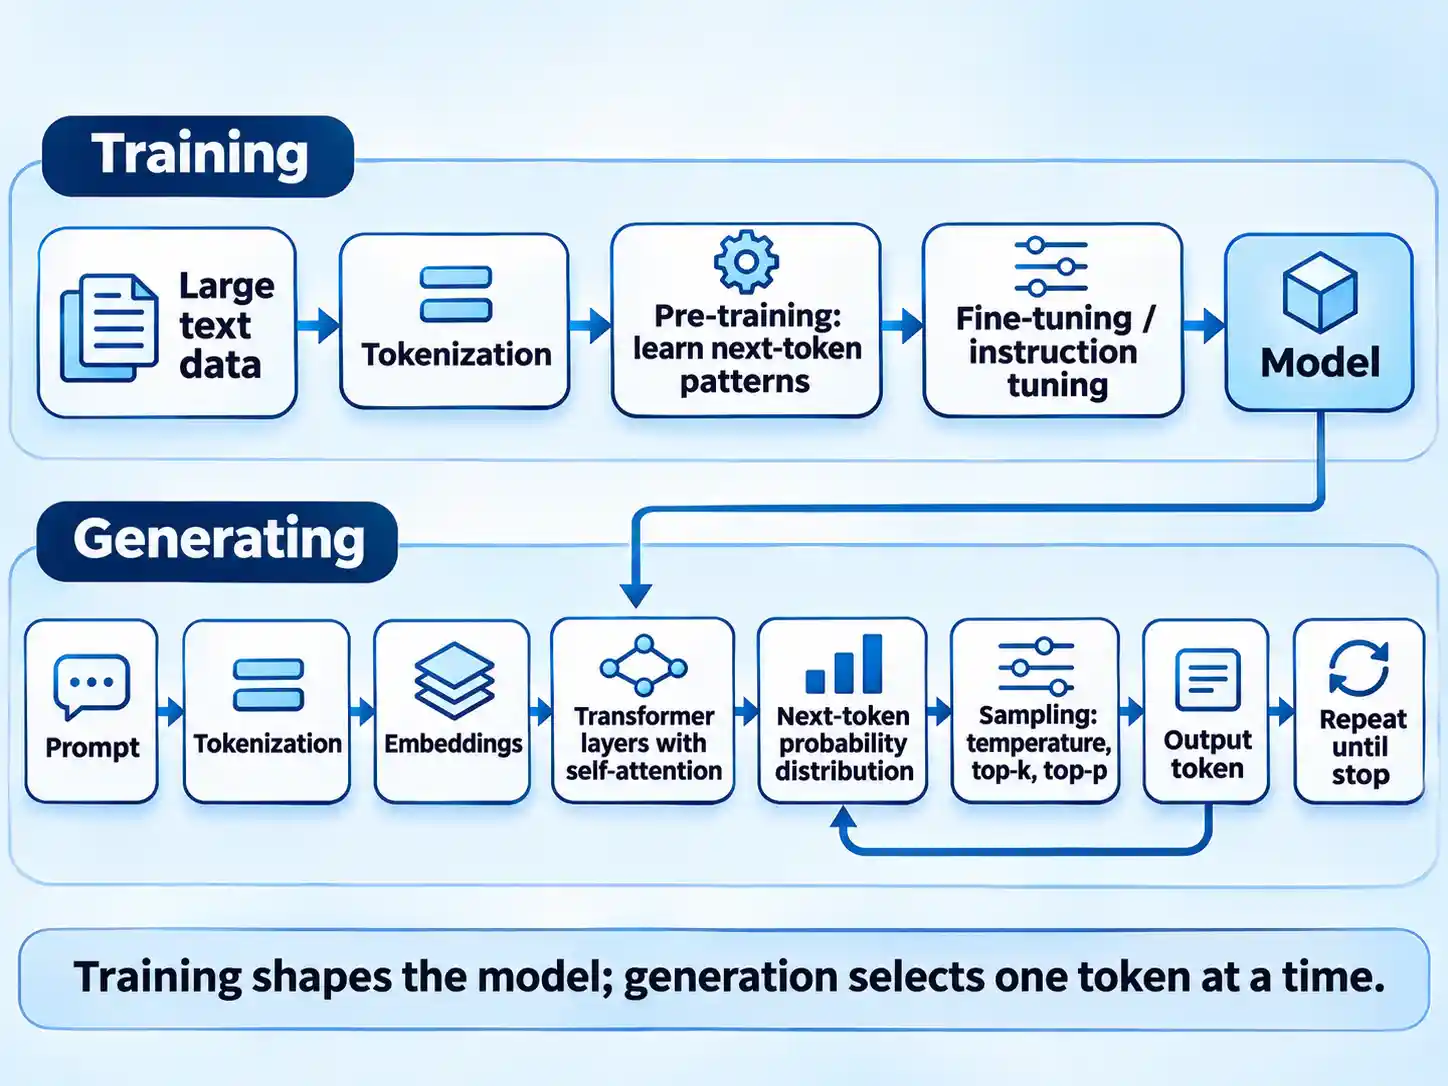
- How it writes: text becomes tokens, tokens become vectors, attention weighs how words relate, and the model samples one probable token at a time.
- Where it fits: translation, summarization, question answering, chat interfaces, and classroom feedback are established application areas.
- What goes wrong: biased or inaccurate training data, weak interpretability, heavy compute costs, and a hard limit on how much text the model can see at once.
- The rule: use it where errors are checkable and stakes are manageable; escalate to human review when mistakes would be costly, hidden, or irreversible.
What an LLM actually is
An LLM is a machine-learning model, typically a neural network, trained on a vast amount of text for natural language processing tasks, especially language generation. That definition covers a lot of ground, so it helps to separate two things people constantly blur together: the model and the product wrapped around it.
ChatGPT, Claude, Gemini, Grok, Qwen, and DeepSeek are chatbot interfaces. BERT, the GPT series, PaLM, LLaMA, and DeepSeek-R1 are models or model families. The chatbot is a piece of software built on top of a model, and that wrapper can add memory and access to web search and other tools that the raw model does not have on its own. Two products can feel wildly different while running on models of similar capability, because the harness around the model does much of the visible work.
Info
An LLM is a model class that products are built on top of. “The model knows” is a convenient phrase for a system that produces likely text. Knowledge-like behavior comes out of pattern prediction, so it is only as good as the data the model learned from and the context you supply.
A short lineage: from transformer to today’s model families
The history matters mainly because it explains why one architecture took over the field.
- 2017: Google researchers introduce the transformer architecture in the paper “Attention Is All You Need” at NeurIPS, replacing the sequential processing that limited earlier language models.
- 2018: BERT arrives as an encoder-only model built for understanding text, and GPT-1 appears as a decoder-only generator.
- 2019–2020: GPT-2 draws wide attention, then GPT-3 pushes scale further.
- Late 2022: ChatGPT puts a conversational interface on top of an LLM and reaches a mass audience.
- 2023: GPT-4 adds multimodal capability; OpenAI does not disclose its architecture or parameter count.
- Early 2025: DeepSeek-R1 is released as an open-weight model, joining families such as PaLM and LLaMA in a crowded field.
Treat those names as background. The model landscape shifts quickly enough that any ranked list ages badly, and the name on the box tells you less about your outcome than the task and the review process around it.
How they learn: pre-training and fine-tuning
Training happens in stages, and each stage solves a different problem.
| Stage | What happens | What it produces | What it leaves unproven |
|---|---|---|---|
| Pre-training | The model reads an enormous text corpus and repeatedly predicts the next word or token, adjusting its internal weights each time it is wrong. This is the expensive, compute-heavy phase. | Broad, general patterns of language: grammar, tone, common phrasing, and the statistical shape of how ideas appear together. | Whether a stated fact is true, what happened this morning, or what any particular document says. |
| Fine-tuning and instruction tuning | The pre-trained model is trained further on curated examples, often prompt-and-response pairs, so it learns to follow instructions and behave as an assistant. | A model that answers requests, respects formats, and behaves predictably in conversation. | Reliability on facts. Instruction tuning changes behavior and formatting, and it installs no fact-checking layer. |
Pre-training teaches a model to understand and generate human language in general, which is why the second stage is so much cheaper than starting from scratch. Fine-tuning specializes an already capable model for a domain or a task. A team that wants a support assistant fine-tunes; a team that wants a general-purpose language model builds across tournament reporting for it.
A mental shortcut that causes trouble is imagining a hidden library inside the model. What sits inside are weights, shaped by text, that make certain continuations far more likely than others. When the model writes “the meeting is on Tuesday,” it is completing a pattern that fits your prompt. If that detail never appeared in your message, the pattern may still resolve with total confidence.
How they generate text: tokens, attention, and sampling
Generation is a loop, and it runs at a scale that makes the result feel instant. Here is the sequence that unfolds between your prompt and the first visible word.
- Tokenization. Your text is broken into tokens, which are usually subword units rather than whole words. “Unhappiness” might become “un,” “happy,” and “ness.” A subword tokenizer uses algorithms such as Byte Pair Encoding, WordPiece, or SentencePiece to build a fixed vocabulary of 32,000 to 100,000 tokens in typical modern models.
- Embeddings. Each token is converted into a dense vector in a space with hundreds or thousands of dimensions. Words with related meanings cluster together, which is how the model handles a paraphrase it has never seen verbatim.
- Attention. Transformer layers look at the whole stretch of text at once and learn which words matter to which other words. In “The cat sat on the mat because it was comfortable,” attention is what lets the model resolve “it” to the mat.
- Probability scoring. The final layer produces a ranked set of candidate next tokens with probabilities attached.
- Sampling. The system picks one candidate, using controls such as temperature, top-k, or nucleus sampling to decide how adventurous that pick should be.
- Repeat. The chosen token is appended to the input and the loop runs again, one token at a time, until a stop condition is reached.
Why outputs vary and long inputs fail
Two practical behaviors trip people up more than any other: the same prompt can produce different text twice, and a document that is too long quietly stops being read.
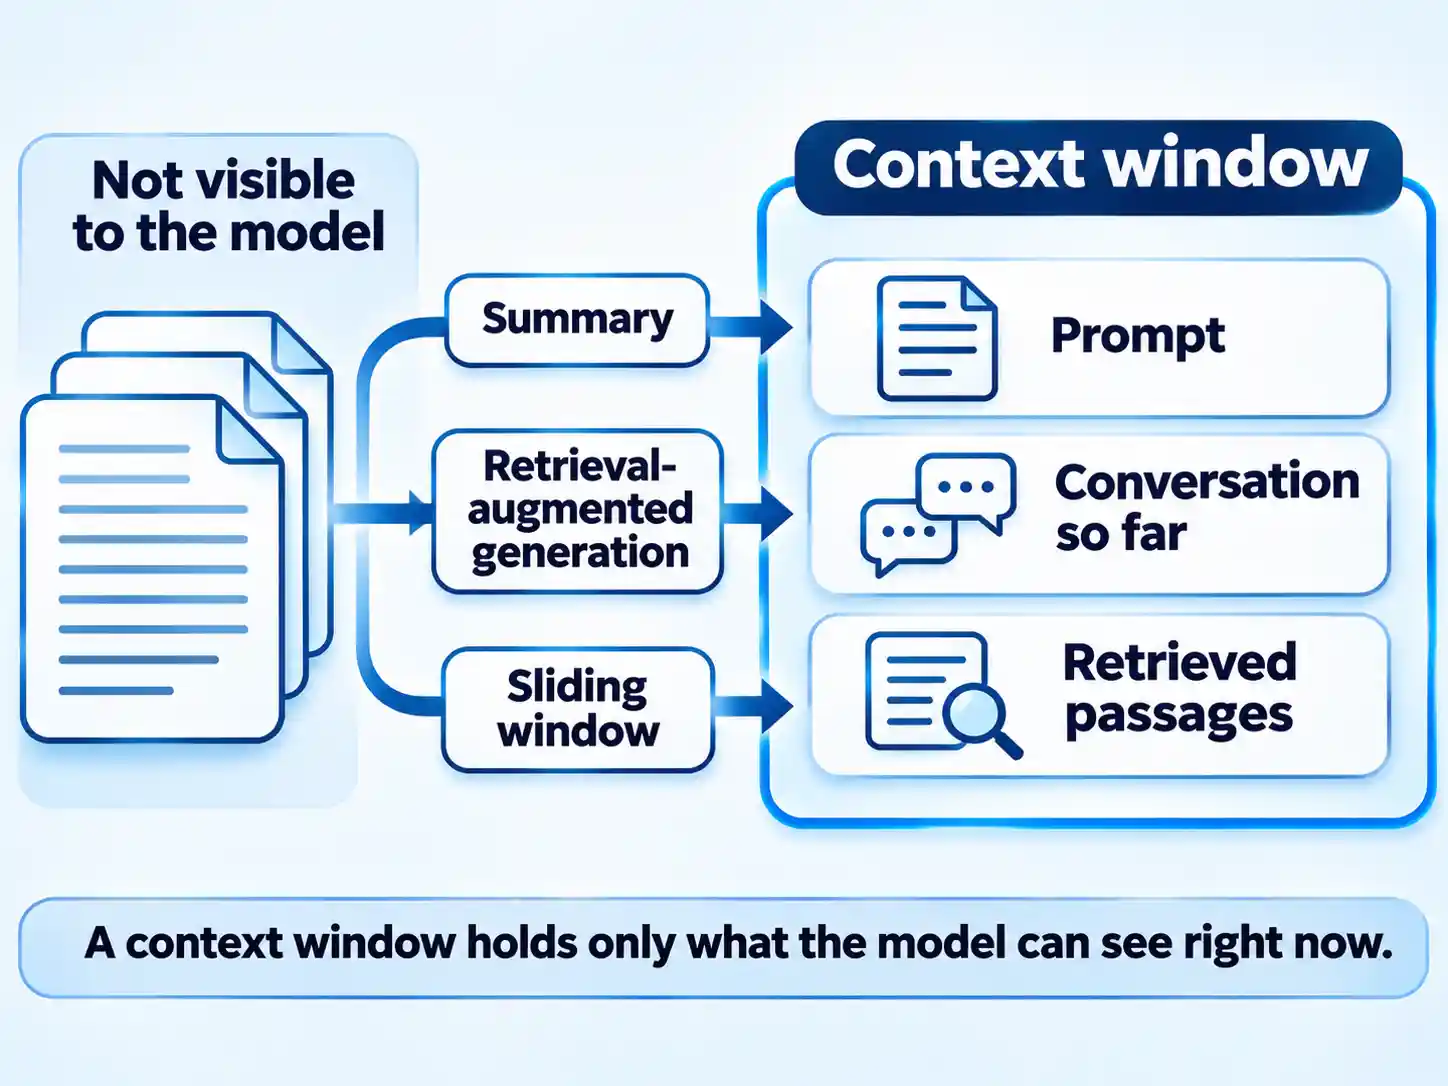
Every LLM has a context window, which is the maximum amount of text it can consider at once. Think of it as working memory. Anything outside that window effectively does not exist from the model’s point of view, which is why a long conversation eventually loses its early detail and why an oversized document can be summarized from only its first portion. Teams work around this with conversation summaries, retrieval-augmented generation that pulls relevant passages into the prompt, and sliding-window techniques that process a document in overlapping chunks.
| Control | What it changes | Likely effect | Watch out for |
|---|---|---|---|
| Context window | The total text the model can hold at once, including your prompt, the conversation so far, and any retrieved passages. | Fits more material into a single request. | Content beyond the window is invisible. Long sessions and long files need summaries or retrieval. |
| Temperature at zero | How strongly the model favors the single most probable next token. | Consistent, repeatable, sometimes repetitive output. | Consistency applies to the wording, not the truth. A wrong fact can repeat just as reliably. |
| Higher temperature | How much probability mass lower-ranked tokens receive. | More variety and invention in phrasing. | More drift, more invented detail, harder review. |
| Top-k sampling | Restricts the candidate pool to the k highest-probability tokens. | Cuts off implausible options while keeping some choice. | The right k depends on the task; a fixed value behaves differently across prompts. |
| Nucleus (top-p) sampling | Sets the candidate pool by cumulative probability instead of a fixed count. | Adapts the pool size to the model’s own confidence. | On factual work, a wider pool still includes confident wrong answers. |
These controls are behavioral dials. The setting that suits a brainstorming brief can be the wrong one for a compliance summary, so tune them per task.
Where they fit in real work
LLMs now deliver strong results in machine translation, summarization, and question answering, while the same field carries heavy compute demands and open concerns about interpretability, bias, and transparency. The capability is real, and the caveats are part of the same package.
| Task family | What the model contributes | What a person still checks |
|---|---|---|
| Machine translation | Fast, fluent drafts across languages. | Idioms, legal or regulatory wording, brand voice, and anything where a shifted nuance changes the obligation. |
| Summarization | Condensing long reports, threads, and transcripts into readable briefs. | Whether a material point was dropped, softened, or invented, and whether the numbers survived. |
| Question answering | Drafting explanations and first-pass answers from supplied context. | Names, dates, figures, and citations against a primary source. |
| Chat interfaces | Internal and customer-facing conversational support, with tool access layered on where the product provides it. | Escalation paths, edge cases, and whether a wrapped product has its own knowledge and memory rules. |
| Education feedback and question generation | Automated feedback on student work and draft practice questions for instructors. | Accuracy of the subject matter, fairness across students, and pedagogical judgment. |
None of this is a guarantee, and healthcare is the clearest caution. LLMs appear in medical education contexts; diagnostics and treatment recommendations are a different matter and should not be inferred from that. A model that writes a plausible clinical note has demonstrated fluency in clinical language, and nothing more.
When you want the wider landscape before you match a task to a tool, this overview of large language models works as a starting map. The job in front of you still decides what you reach for.
Limits, misconceptions, and the human-review rule
Disappointment with LLMs often traces back to a handful of false assumptions, and each one has a practical correction.
| Misconception | What is actually happening | Practical response |
|---|---|---|
| “It looks up the answer.” | The model scores likely next tokens from learned patterns. Retrieval from a verified source happens only when a product adds it. | Check names, dates, figures, and citations against a primary source before they leave your desk. |
| “It remembers our earlier sessions.” | A fresh session starts without prior context unless a separate memory or retrieval system supplies it. | Restate the essentials, or use a product whose memory behavior you have actually confirmed. |
| “The highest benchmark score wins.” | Benchmarks attempt to measure reasoning, factual accuracy, alignment, and safety under test conditions. | Run a small set of representative tasks from your own work and compare the outputs. |
| “Fluent means accurate.” | Fluency comes from pattern prediction and is independent of factual correctness. | Treat polished prose as a draft to verify, especially when it reads best. |
The structural limits matter just as much. Biased or inaccurate training data can make output less reliable in ways that are hard to spot from a single response. Interpretability remains an open concern, and explaining exactly why a model produced a particular sentence is difficult. Training and deployment carry high computational demands, and transparency about how a given system was built remains a recognized challenge.
Warning
Do not let a model act as the final authority on medical, legal, financial, safety, or regulatory decisions. In those settings an error is costly, often invisible to the person reading the output, and sometimes irreversible. Accountable expertise has to stay in the loop.
The fit rule: when to try an LLM, when to check it, when to leave it alone
One question sorts many tasks faster than a model comparison: if this output is wrong, how would I find out, and what does it cost me?
- Try it directly when the output is cheap to verify, a first draft saves real time, mistakes surface quickly on a read-through, and a person reviews the final version.
- Add a structured review step when the output feeds a decision, reaches a customer, or is published under your organization’s name. Give the model the source material it needs, then check the claims that carry weight.
- Keep it out of the decision seat when errors would be consequential, hidden, or hard to reverse. A model can prepare material for an expert, and the expert still makes the call.
Workflow design deserves attention alongside model choice. A modest model given useful source material, a clear instruction, and a review checklist can produce solid work. Remove those supports, and even a capable model can disappoint. The context you supply and the check at the end are part of the quality equation, not an afterthought.
The takeaway: pair every fluent draft with a check
Large language models are remarkable text machines. They translate, summarize, answer, and draft at a speed no team can match, and they do it by predicting one probable token after another from patterns learned across an enormous amount of writing. That sentence explains the capability and the risk at the same time.
So choose tasks where a fluent draft is worth something and a mistake is catchable. Feed the model the material it needs, keep consequential claims on a short leash, and route anything costly, hidden, or irreversible to a person who owns the outcome. Model selection is the last decision you make; the workflow around the model is the one that determines whether the output helps or hurts.

💬 Comments